
Pricing
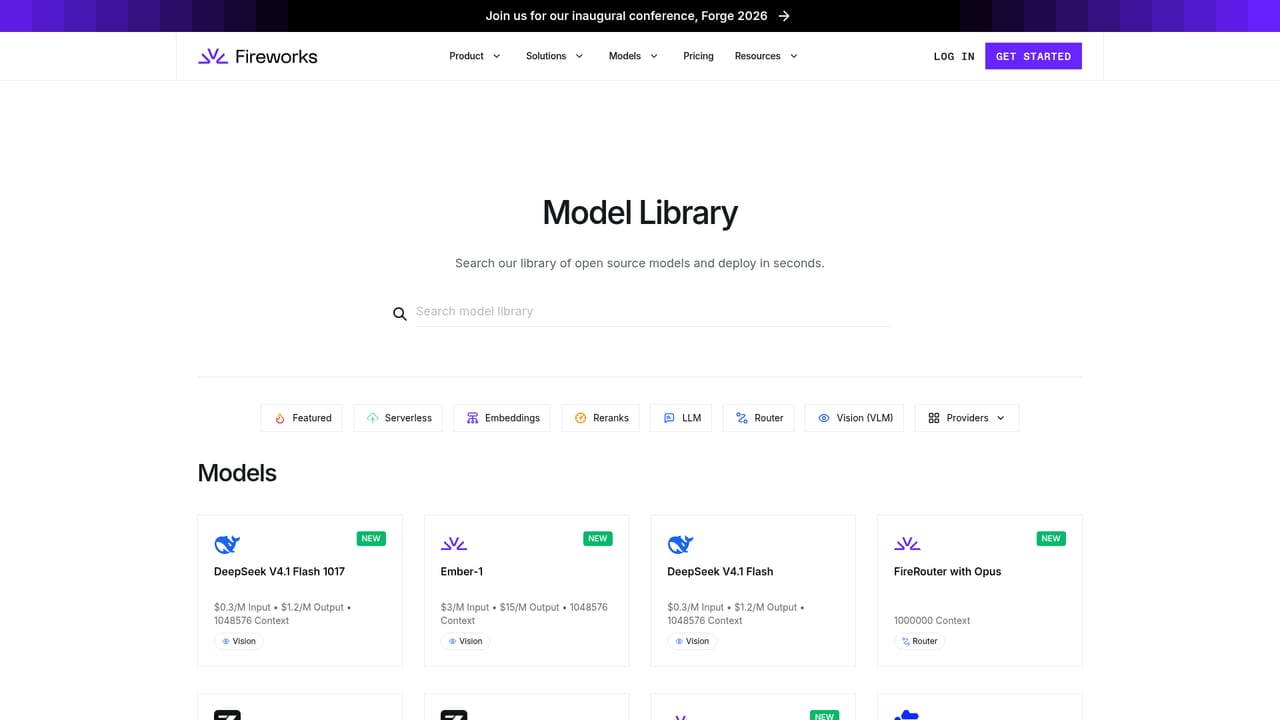
The homepage does not publish a plan grid. Serverless inference is billed per token with Priority and Fast options, individual model pages list input and output rates (for example GLM 5.3 Flash at $0.15 per million input tokens and $0.5 per million output), and On-Demand and Reserved deployments are quoted through sales.
Learn more


