Pricing
The evaluation page does not state prices. It links to a separate pricing page and offers a sales demo for larger teams.
Learn moreOffline and online evals for testing LLM apps and AI agents
Own LangSmith Evaluations? Verify ownership to get a dofollow link

LangSmith Evaluations is LangChain's platform for testing LLM apps and AI agents with offline dataset evals, online monitoring, expert feedback and team prompt iteration, aimed at catching regressions before users see them.
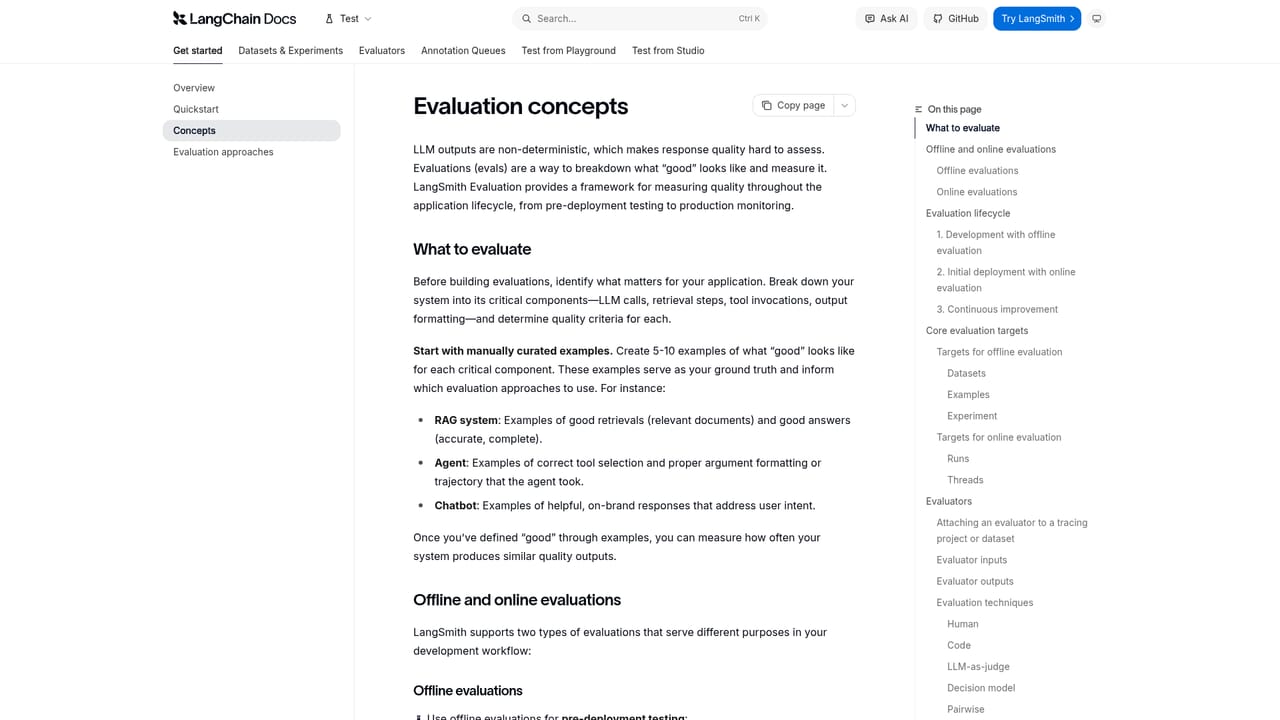
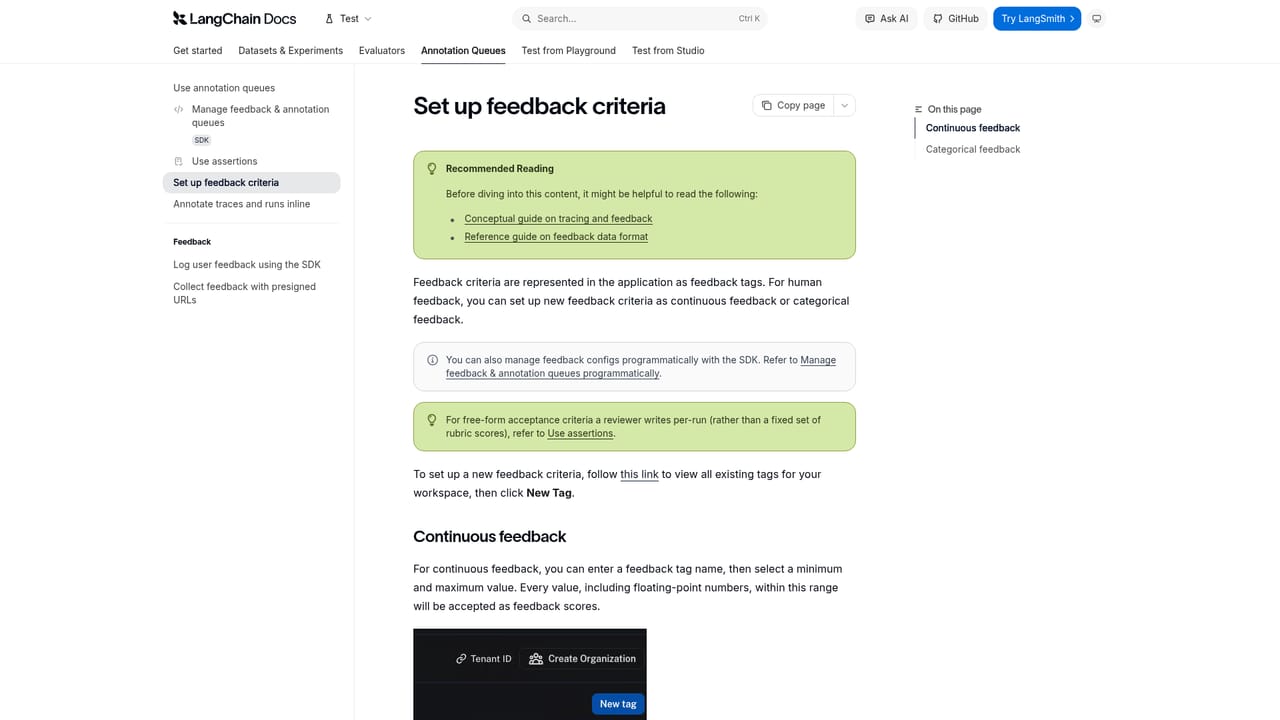
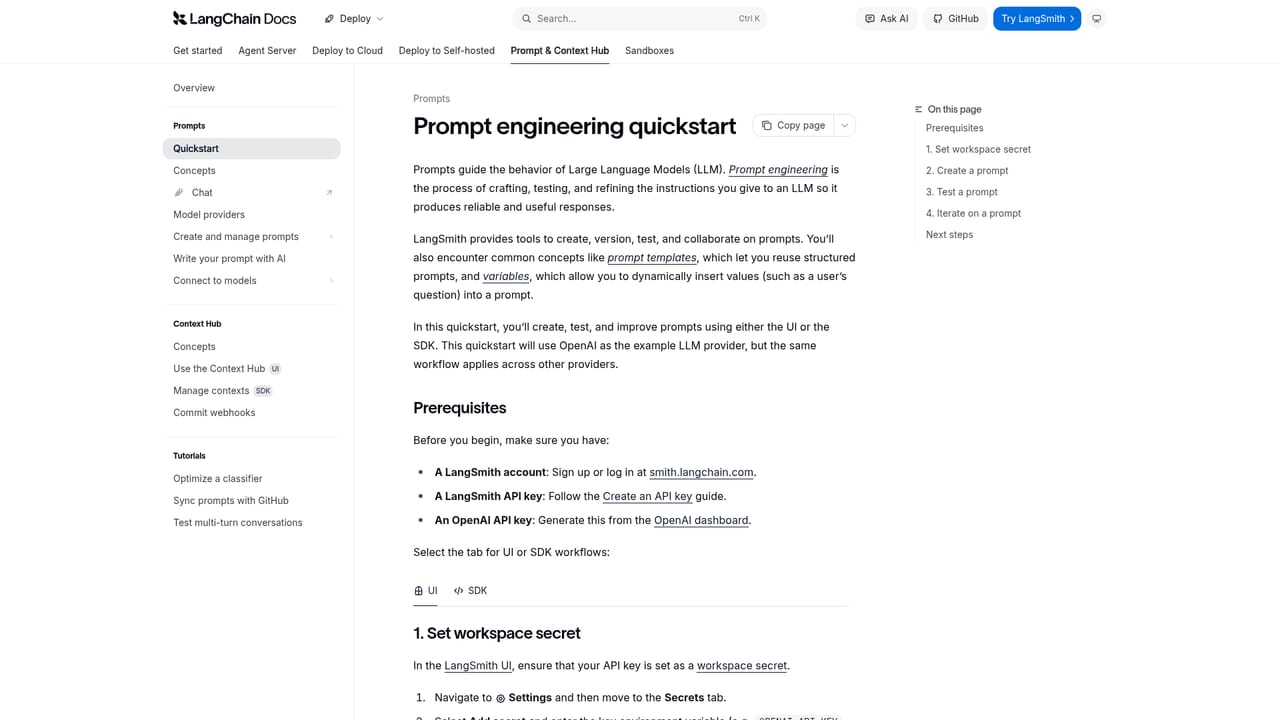
LangSmith Evaluations is the testing and quality layer of the LangSmith platform from LangChain. It is built for teams that ship LLM applications and AI agents and need evidence that a change made things better rather than worse. The page frames the job as continuous quality improvement: run evaluations before and after release, collect expert feedback on how an agent performs, and refine prompts together with colleagues. In practice the workflow splits into offline and online evaluation. Offline evals run against curated datasets during development, so a prompt edit, model swap or code change can be scored against the same reference cases before anything reaches users. Online evals extend the idea to live behavior, helping teams monitor quality once an agent is in production and trace failures back to the step that caused them. The stated aim is to catch regressions before users do, which makes the tool relevant to hallucination checks, where an answer has to be compared against expected or grounded results. The product is aimed at engineering teams building agents, including those using LangGraph, though the homepage presents it as a platform rather than a framework add-on. Supporting material includes documentation on evaluation concepts, a guide to setting feedback criteria, a prompt engineering quickstart, a testing ebook and an introductory course on LangChain Academy. A self-hosting guide for Kubernetes is also listed, which points to deployment options beyond the hosted service. Customers named on the page span fintech, travel, enterprise software, healthcare and hardware, suggesting use at larger organizations as well as startups. Among alternatives, LangSmith Evaluations sits with other LLM observability and evaluation platforms. Its main advantage is that datasets, prompt iteration, human feedback and evals live in one workspace tied to the LangChain ecosystem. Teams that do not use that ecosystem, or that want a lightweight open-source test runner, should weigh how much of the platform they actually need. The homepage excerpt does not detail specific scoring methods, so evaluators and metrics should be confirmed in the documentation.
The evaluation page does not state prices. It links to a separate pricing page and offers a sales demo for larger teams.
Learn moreDocumentation, a LangChain Academy intro course, a testing ebook and a contact-sales demo option are available.
Learn moreThe page references LangGraph-built agents and a Kubernetes self-hosting option. No other integrations are listed in the provided content.
Learn moreOffline evaluations on curated datasets, online evaluations for production quality, expert feedback collection on agent performance, team prompt iteration, and debugging of agent failures to catch regressions before release.
Learn more


