OmniHuman 1.5 turns one photo and an audio clip (up to 30 seconds) into a lip-synced digital human video with emotional acting, gesture, and optional text-prompt direction. It supports humans, anime, and pets, handles singing and multi-character dialogue, and runs on a prepaid credit model.
OmniHuman 1.5 is an AI digital human model that converts a single still image and an audio track into a video performance, complete with synchronized lip movement, facial expression, gesture, and camera motion. The workflow is deliberately short: upload a portrait in JPG, attach a voice clip or song of up to 30 seconds, optionally describe the effect you want in a text prompt, pick 720p or 1080p, and generate. No animation skill or rigging is required, and the company pitches it as prompt-free by default, with text prompts used only to refine direction.
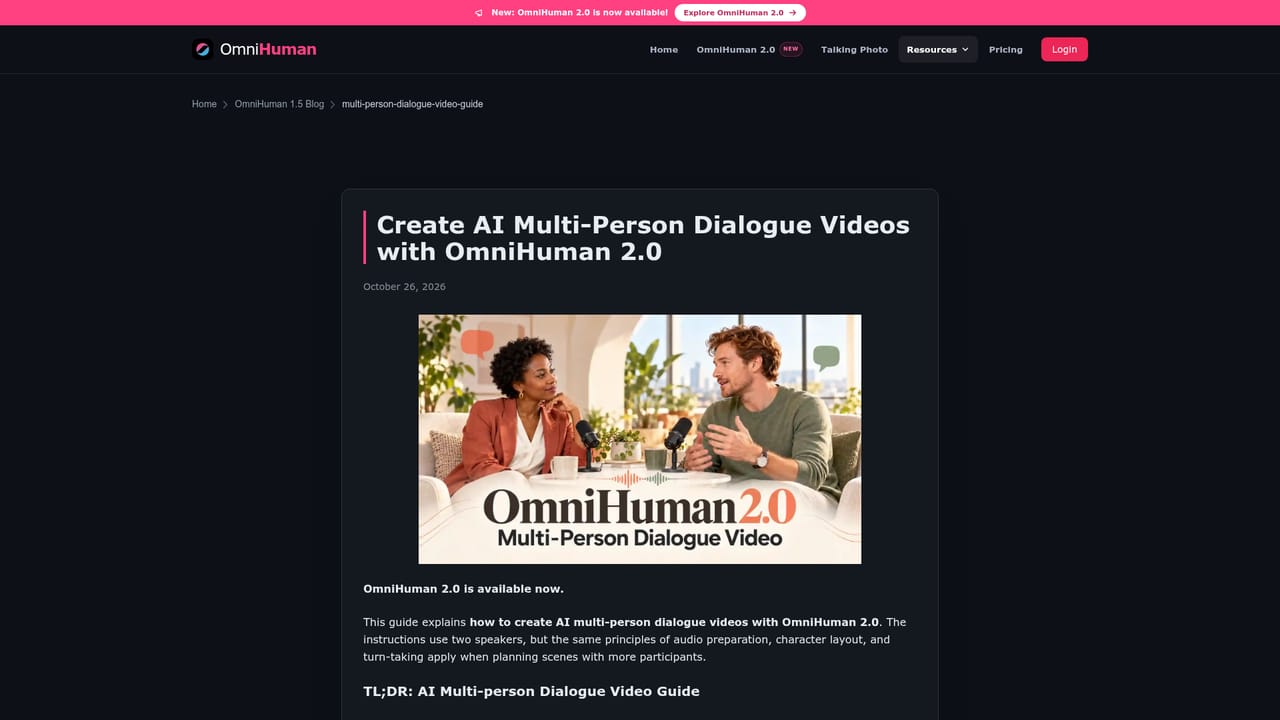
The subject does not have to be a real person. The model handles anime portraits, stylized characters, and pets, which puts it in the same bracket as VTuber animation tools and virtual influencer platforms. Two features distinguish it from simple talking-head generators. First, rhythmic performance: it reads pace, breathing, and natural pauses from the audio, so singing clips work alongside speech. Second, multi-character scenes, where separate audio tracks are routed to different faces inside a single frame to produce duets, interview formats, and group dialogue. A prompt guide covers how to steer camera moves and actions, and a blog walks through multi-person dialogue production.
Practical uses named by the vendor include music covers and virtual idols, short cinematic scenes, branded presenters and product explainers, skit and interview reels, and educational or training videos with a digital instructor. The realistic buyer is a solo creator, social media producer, or small studio that needs performer footage without booking talent, and the 30 second audio ceiling keeps output aimed at short-form rather than long narrative work.
Positioning matters here. OmniHuman 2.0 is already available from the same site, accepts audio up to five minutes, and uses audio context to drive actions, so 1.5 is best understood as the quicker, shorter-clip entry point that still shares the credit balance. Buyers should weigh it against dedicated avatar suites and general video generators: OmniHuman is narrow and performance-focused, trading breadth of editing tools for stronger lip-sync and emotional acting on a single portrait.